2026 CDO Report: Meet the Modern Data Team New survey of VP & C-level data and AI leaders confirms what’s stalling AI transformation.
Webinar | The 2026 Data & AI Compensation Benchmark: What Executive Talent Is Really Worth From compensation benchmarks to organizational influence, uncover what the market reveals about the evolving data and AI executive role.
What Is a Chief Data Officer in 2026? Many people working within the data industry are saying the same thing: the role of the Chief Data Officer (CDO) has changed – but how? CDO Magazine began an expert survey to find out. We recent...
Leadership
From Trusted Content to AI-Ready Data: How Wiley Is Building a Data Products Business
Armughan Rafat, Chief AI & Data Analytics Officer at Wiley, shares how the company is turning trusted content into AI-ready data products and what that work could mean for data leaders.

Written by: Marcy Tillman, Director, Content Strategy | CDO Magazine
Updated 10:00 AM EDT, October 1, 2026
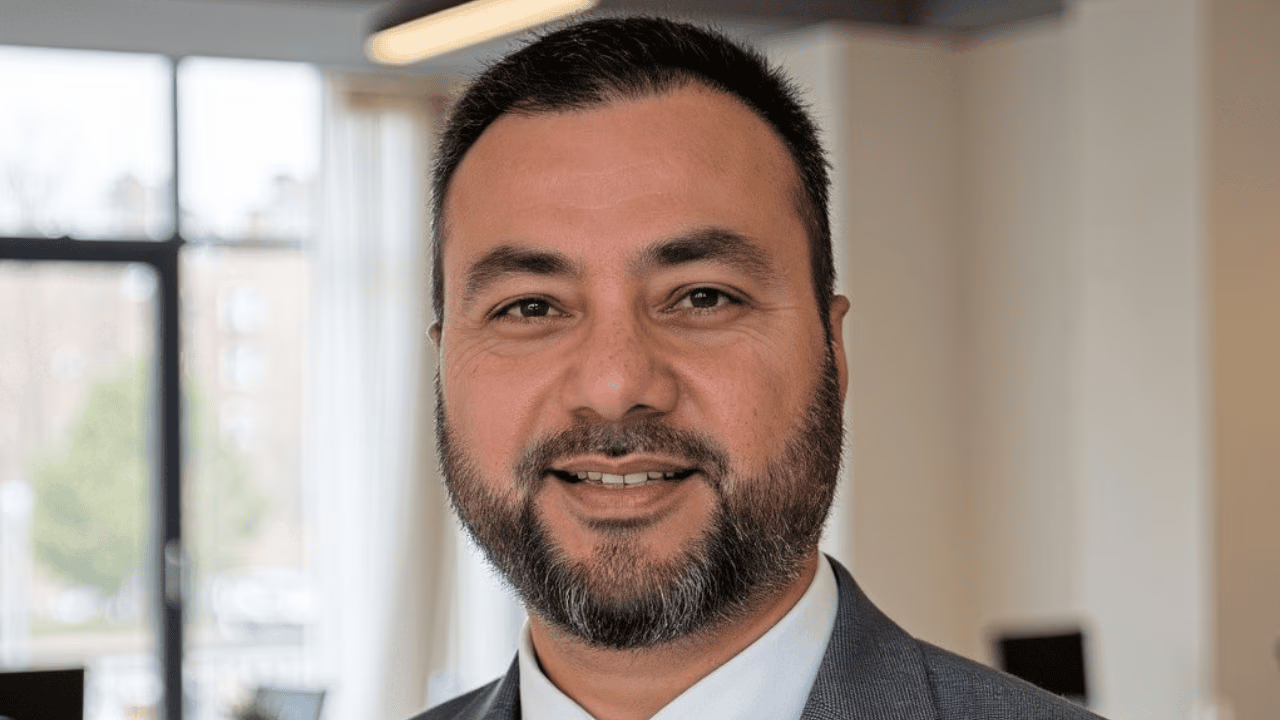
For more than 200 years, Wiley has worked to make knowledge trustworthy and usable. Today, that includes making the same knowledge usable by machines as well as people.
Armughan Rafat, Chief AI and Data Analytics Officer at Wiley, is helping lead that work. His focus is on turning Wiley’s trusted content into AI-ready data products for corporate R&D and AI developers.
In this Q&A with CDO Magazine, Rafat shares how Wiley is approaching that work and what he thinks it could mean for the role of the data leader.
Q: How have you defined your mandate, where did you start, and what prepared you for it?
My mandate is to develop and commercialize AI-ready content and data products for AI developers and corporate R&D teams, turning Wiley’s trusted content into actionable intelligence for the professionals who are doing things like developing drugs, improving healthcare outcomes, engineering new materials, and advancing chemistry in labs around the world.
I’d frame “where I started” with an observation. There are two loud camps on AI in research right now, and both are wrong. One camp believes AI can do everything, fill any gap, and that good enough is good enough. The other looks at all of it with suspicion.
The truth is that AI is genuinely good at synthesizing volumes of evidence no person can keep up with. But generative AI is built to fill gaps, and when it finds one, it fills it. So the discipline — and frankly the value — is pointing it at sources you trust and making it answer only from those sources.
My whole career prepared me for exactly that: Chief Analytics Officer at Norstella, Chief Data Officer (CDO) at Clarivate, and before that at Thomson Reuters building and selling data-driven products. I have spent about 20 years in the data and analytics field, and every one of those roles was about turning content and data assets into products customers need and pay for.
Before I arrived, Wiley was already on the journey to transform its content into the data and AI products professionals need and had already built licensing relationships with leading LLM developers and strategic partnerships with AI innovators like Anthropic, AWS, Perplexity, and Mistral AI. In the seven months since I joined the company, we’ve progressed in that journey, providing vectorized scientific information to leading companies for their targeted use cases.
Q: Is the goal incremental revenue, or a new operating model? What does the end state look like?
The goal is a growth engine that compounds — not just one-time revenue. One-time licensing proves demand and funds the build; recurring revenue is where this is heading. In our last fiscal year, we reported that AI revenue rose from $40 million to $49 million year over year (up 23 percent), with recurring AI revenue expanding from $1 million to $8 million. We expect over $50 million in AI revenue in fiscal 2027, with recurring revenue continuing to expand rapidly.
But the end state isn’t a number. The end state can take many forms, and the goal is always the same: for professionals to have trusted, human-validated information and analysis at the exact moment they need it. There are too many potential applications to name — innovations in food and agricultural sciences, better understanding of disease progression and potential treatments, driving breakthroughs in materials science, and much more.
And there’s a lesson in this for every data leader reading this: the job has moved from governing data to commercializing it. If you don’t own the outcome — the product, the customer experience, and the investments — you’re running internal analytics. That’s valuable, but it’s not a growth engine.
Q: What decisions do these products improve — who is the user, the buyer, the budget holder?
Given the breadth of our content and expertise, this spans many audiences, so let me make it concrete with three examples.
In healthcare, working with OpenEvidence, we reach physicians at the point of care, so clinical decisions are grounded in the latest peer-reviewed evidence. Through this partnership, Wiley provides a comprehensive portfolio of scientific and medical content to OpenEvidence, including the Cochrane Database of Systematic Reviews — the home of gold-standard evidence syntheses — and hundreds of Wiley’s peer-reviewed journals and resources across key medical specialties.
In pharma, our Clinical Outcome Assessments (COAs) are validated ways of measuring how a patient feels, functions, or survives — often used in clinical drug trials to determine how a treatment impacts a patient. Regulators around the world are placing growing weight on these assessments, which has turned COAs into essential infrastructure for clinical trials — and it’s an area where we’re growing our capabilities significantly.
In the lab, our spectral analysis APIs serve laboratories identifying unknown compounds — catching a quality issue on a production line, or a forensic case where a delayed analysis holds everything up. There, the analytical chemist is the user, and the instrument vendor or software platform embedding our data is the commercial buyer and budget holder.
The breadth is real. As we noted in our June earnings, of 19 corporate customers, 12 are in life sciences, four in engineering, materials, or chemistry, two in financial services, and one in agricultural and food science — including seven of the top 10 global pharmaceutical companies. Our use case runway is substantial.
And what all of these buyers share is the same problem. Today, a researcher pulls from five, six, 10 different platforms, and each one is hardwired to its own data, so it can only answer from what it holds. Reconciling that is a small data project every single day. A substantial share of a researcher’s time goes to finding the right papers and pulling the detail out of them.
That’s the budget holder’s argument: it’s time already being paid for.
Q: Walk us through one paper becoming a living data product — structured, enriched, updated, commercially usable.
Take a researcher working on Alzheimer’s, sitting on top of roughly 86,000 papers on the disease. A single paper on an amyloid-targeting drug program starts as raw text. We structure and tag it with identifiers and metadata, enrich it with rights and provenance, and connect it into a knowledge graph alongside clinical trial data and other sources.
From there, a repeatable research methodology — authored by our own editorial and subject-matter experts — matches the researcher’s question to the right method, retrieves and cites the relevant programs with provenance, and surfaces the points where the evidence conflicts so a human can make the call. What comes out the other end is a structured report with a full audit trail back to source.
Notice there’s a human in the loop twice in that story, and that’s the part that is hard to replicate. When the research is produced, peer review puts an expert in the loop to review the results. When it’s consumed, every claim points back to that source so a person can check it again. Both ends are checked.
And here’s why the full text matters: most AI tools read abstracts, because abstracts can be easy to get. An abstract tells you what a paper is about — it doesn’t give you the experimental detail or the causal mechanism, and that’s where the connections live.
We tested this with Biorelate, a company focused on curation of biomedical information. Their AI model analyzed a sample of our full-text articles alongside publicly available PubMed Central abstracts. Reading full text identified 82 percent more causal relationships than reading abstract and title alone, and Wiley’s content specifically delivered nearly 160,000 unique biological relationships that exist nowhere else in the literature.
That’s the difference between digitizing a paper and turning it into a living product.
Q: Across 200 years of changing formats and vocabularies — how do you create machine-usable entities without losing disciplinary context?
For 200 years, our job has been to take knowledge and make it trustworthy and usable: peer-reviewed, properly attributed, consistent, and easy to find. The formats kept changing, from print to digital, but the underlying discipline never did — take work people can trust, and make sure others can find it, cite it, and rely on it.
The current version of that job is making the same knowledge usable by machines as well as people. That means giving each concept a consistent structure and a shared vocabulary so software can read it reliably. The work isn’t acquiring more data — it’s making what we already have machine-readable, interoperable, and rights-clear. Structure, ontologies, entity resolution, and clean APIs are what turn an archive into a product.
The difficult part is doing that while keeping the scientific context intact. A concept only holds its meaning if you preserve what sits around it: how it was defined, where it came from, the population it applies to, and the evidence behind it. We treat that context as part of the entity itself, so it travels with the data rather than being flattened away.
What lets us do this credibly is that we are not working from raw data. We hold the peer-reviewed source material, and we have long-standing relationships with the scholarly communities that produced it. That’s what makes the result authoritative rather than merely tidy.
COAs are the clearest example. These are the established, peer-reviewed measures that clinical trials use to decide whether a treatment actually works across areas like dermatology, immunology, and neurology — measuring outcomes such as whether a patient’s skin has cleared, their symptoms have eased, and their function has improved. A single trial can cost hundreds of millions and hinges on getting these measures right, so the exact version, wording, and scoring matter enormously. We hold the rights to a large set of them, and our role is to keep each one authoritative, consistent, and ready to use in trials anywhere in the world — all the way through to the evidence a regulator sees.
Q: What is the shared data foundation behind these products — and how do you avoid legacy platform constraints?
Let me start with a number that should stop every R&D leader in their tracks. A Google DeepMind and MIT FutureTech study released in September 2026 surveyed more than 600 scientists across the US and UK about how they actually use AI in their research. Nearly all of them save time using it. But for 46 percent of them, checking that output ate up more than a quarter of the time AI had saved them.
The researchers gave this phenomenon a name: the “verification tax.” We’re seeing the same pattern in our own research. Wiley’s ExplanAItions study found that 84 percent of researchers now use AI in their work, nearly half of them weekly. At the same time, concerns about these models climbed to 87 percent, up from 81 percent just a year earlier. The more researchers use AI, the less they trust it.
Today’s general-purpose models are a mile wide and an inch deep: extraordinary at breadth, but when a pharmaceutical team is working a therapeutic area, the answer can’t come from a forum thread. It has to come from the experimental detail in the peer-reviewed record, and it has to be traceable back to it.
So I’d say that any trusted research intelligence platform requires three layers.
First, trusted knowledge: where the corpus actually comes from, and whether it reaches beyond papers into clinical trials, taxonomies, disease and procedure codes, patents, research grants, and conference proceedings. Research papers alone are not enough, and that’s where most knowledge layers stop. Assembling that connective tissue is expertise work, not a data-volume problem.
Second, the model: whether it is specialized enough to understand the domain it’s operating on. Providing the sources is one thing; knowing how to reason over them is another.
Third, deployment: whether the customer controls which sources are used, and whether their own proprietary knowledge can be brought in without leaving their environment or training anything that serves someone else.
In practice, our Knowledge Feeds represent that foundation: vectorized content where the most relevant chunks are returned with metadata — so the AI agent has context. We rebuilt them from the ground up. Direct API integration and MCP server access are now built as part of the platform, not an afterthought, bringing speed and flexibility to the research or discovery process.
And the spectral analysis portfolio is that approach in production: four APIs putting curated reference data and analytical models directly into lab, vendor, and platform systems — vendor-neutral and built for interoperability.
Q: What had to change in Wiley’s operating model to make room for this business?
The first thing to understand is that these growth initiatives are complementary to and embedded within our core Research and Learning businesses. The content our expert teams publish is the basis for the analysis and knowledge layers we deliver to clients.
There’s also a feedback loop the other way. By working with industry and corporate organizations, we have the opportunity to better understand what their needs are and, where appropriate, pass that information back to our editorial teams, so the research engine can more directly support real-world outcomes.
Structurally, we’ve set up a strategic initiative focused on AI and Data Analytics to take this work forward, and new initiatives now move through the same kind of business-case approval as any other investment.
That discipline is what separates a growth engine from a science project.
Q: Who needs a seat at the table, what does each function contribute, and who owns the product end to end?
The teams that succeed build like a product organization, not a data organization — data engineering, product management, and domain experts in the same room. At Wiley, that means scientists and editors sitting with engineers.
On Knowledge Feeds, that showed up as our AI and Data Analytics group, the Technology and Operations engineering team, and the product team all shipping together rather than through separate handoffs. When these handoffs disappear, quality goes up and cycle time goes down.
Q: What does the scorecard for a scalable data-products business look like?
I’d point to three kinds of proof.
First, commercial proof: recurring revenue and renewals. As we’ve reported, COA revenue grew from $700,000 in fiscal 2021 to $6.5 million in fiscal 2025, and then jumped 68 percent this year to $11 million — and we expect strong growth to continue.
Second, quality of insight: we’ve done work to quantify the value our content provides. Most AI tools ingest abstracts because they’re easily available — but abstracts summarize research; they don’t capture the experimental detail, causal mechanisms, and nuanced biological relationships researchers actually need.
Third, customer outcome: the share of researcher time returned. Half or more of a researcher’s day can go to finding and extracting information. The scorecard that matters most is how much of that time we hand back. We are actively monitoring and quantifying this.
In closing, for corporate R&D, there are three questions to ask about your knowledge layer: 1) Where is the corpus actually coming from? 2) What is building the connective tissue between sources — that’s taxonomy and domain expertise, not data volume? And 3) What sits alongside the papers?
Armughan Rafat is Chief AI & Data Services Officer at Wiley, where he leads the company’s artificial intelligence and data services strategy. Previously, he served as Chief Analytics Officer at Norstella and held senior technology leadership roles at Clarivate Analytics, ASI Family of Companies, and Thomson Reuters. A published innovator with patents in machine learning, Rafat has more than 25 years of experience across life sciences, financial services, and publishing. He holds a bachelor’s degree from Karachi University, a master’s degree from SZABIST, and an Executive MBA from Stevens Institute of Technology.
 Elevate Your Personal Brand


