What Is a Chief Data Officer in 2026? Many people working within the data industry are saying the same thing: the role of the Chief Data Officer (CDO) has changed – but how? CDO Magazine began an expert survey to find out. We recent...
Generative + Agentic AI: Moving From Experimentation to Enterprise Scale Generative and agentic AI are making their way into enterprise production, bringing new questions for Chief Data Officers (CDOs) and other data and AI leaders responsible for making these technologies...
Webinar | The Agentic Mindset Shift: How to Onboard an Agentic Data Team Three sessions, real playbooks, proven results you can replicate.
Data Management
The AI Advantage You Can’t Buy: MetLife’s Tamar Shapiro on the Business Context Layer

Written by: Marcy Tillman | Director, Content Strategy, CDO Magazine
Updated 10:00 AM EDT, October 27, 2026
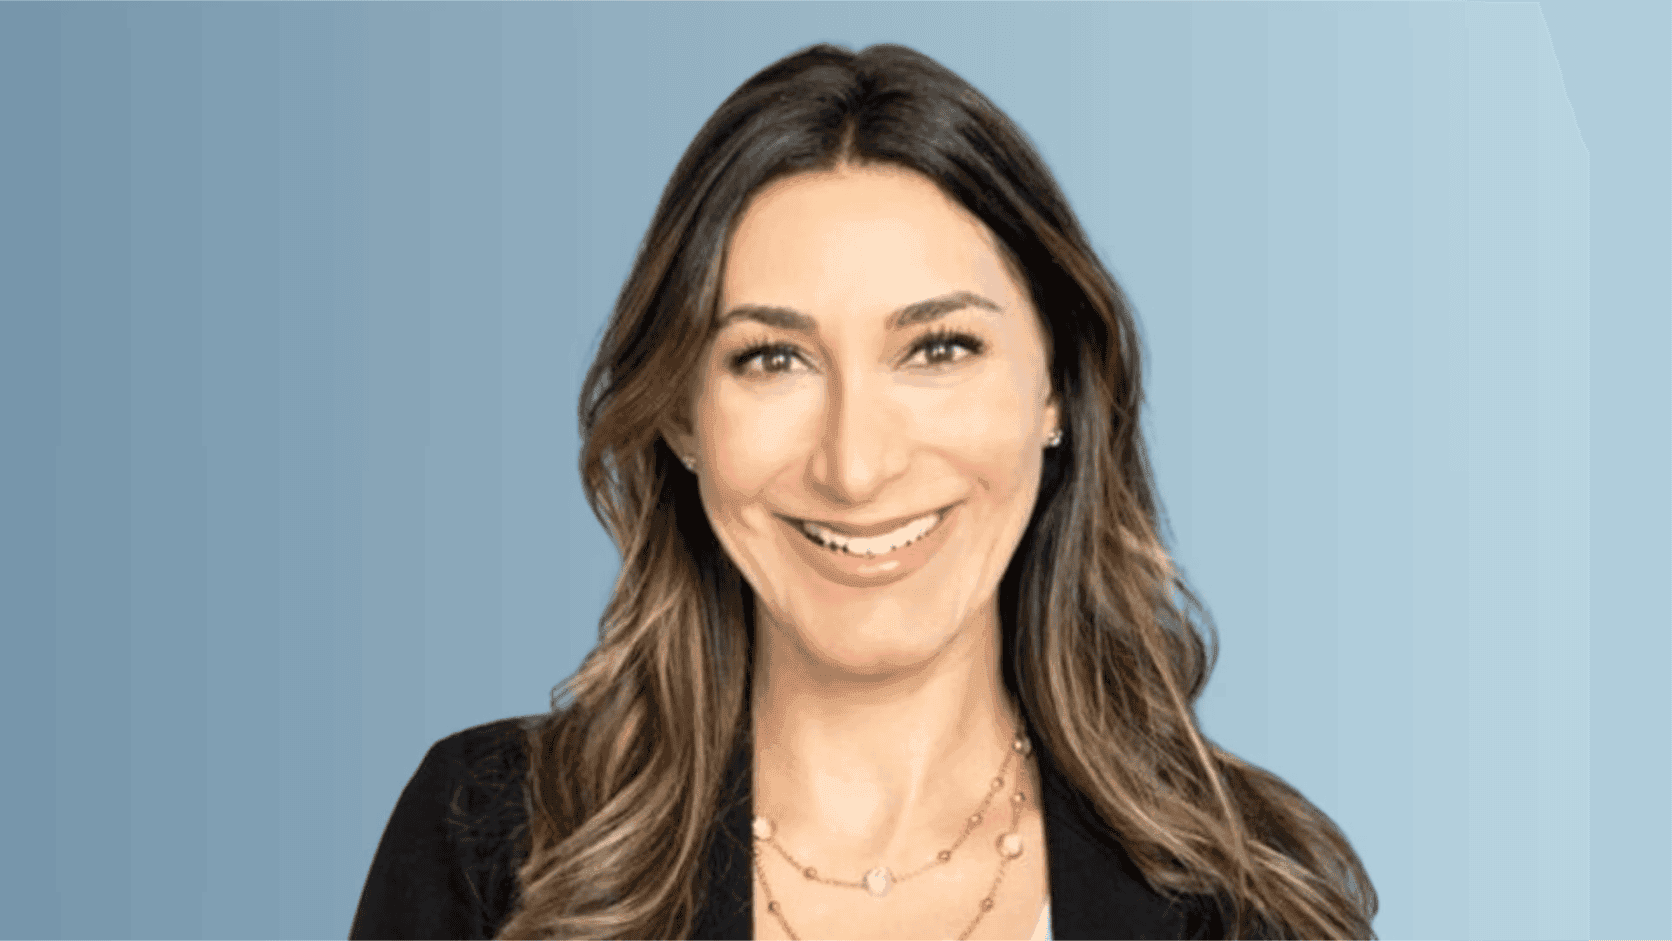
Tamar Shapiro, Global Chief Data & Analytics Officer, MetLife
At MetLife, Tamar Shapiro, Global Chief Data & Analytics Officer, is tackling one of enterprise AI’s hardest problems: encoding the unwritten business rules and exceptions that only veteran employees know.
In this Q&A with CDO Magazine, Shapiro breaks down why clean data isn’t enough, how MetLife is building its business context layer, and why getting definitions right becomes even more critical for Chief Data Officers (CDOs) as AI systems move from answering questions to taking action.
Q: Everyone talks about data quality and AI readiness. Why do you believe business context is the next competitive advantage to win with AI?
Data quality has become table stakes. Over the past decade, most enterprises have invested in cleaning, consolidating, and governing their data. While this work is essential to producing accurate, trusted data, it does not capture the business context and meaning that remain locked in a few subject matter experts’ heads.
AI models themselves are commoditizing quickly. The frontier models available to us are largely the same ones available to every one of our competitors. So, if the model is not the differentiator and clean data is simply the price of entry, then the competitive advantage lies in what sits between them: the proprietary knowledge of how our business operates.
In insurance, this knowledge is vast and yet largely uncaptured. Definitions such as what constitutes an active customer, when a policy is considered “in force,” or what “closed” means for a claim or a sale often reside in the minds of people who have been in the company for many years, and in code written by someone who left years ago.
Encoding that knowledge into something a machine can act on and apply is difficult and deeply institutional work, which is exactly why it’s defensible and why nobody can buy their way past it.
Q: You’ve described a context layer as a strategic investment. What is it, and why is it so important for AI?
A context layer is what tells an AI system what your data actually means: the business concepts, how they relate to each other, and the agreed definition of every measure that matters. It is not simply a piece of technology but an encoded version of what your best people already know.
At MetLife, we see the context layer as a strategic investment for two reasons.
The first is economics. Without it, every AI use case pays its own context tax. The same definitions are re-derived, the same joins are rebuilt, the same business rules are re-encoded, and each use case does it slightly differently. That’s expensive in terms of time and resources, and it’s expensive from a token usage perspective. When a model must interpret raw, unexplained data, it burns real compute, doing work that you could have done once, upfront, and at a lower cost. Ambiguity now carries a per-query price, and you pay it every time anyone asks.
The second reason is even more important. If you do not define meaning, the model will define it for you. Rather than returning nothing, it will usually return an assumption, and it won’t necessarily flag that it made a choice. It infers, and what it plausibly infers may look correct. Yet the same question asked a second time may produce different answers, each defensible, neither reproducible. That inconsistency quickly erodes trust. People may tolerate a system that is occasionally wrong, but they will walk away from one that is inconsistent. Defining the meaning in a context layer puts those decisions back under your control.
Q: Many organizations have spent years building data lakes, warehouses, and governance programs. Why are those investments not enough on their own for AI success?
It’s because we built all of that for an audience that could ask a follow-up question. A data lake or warehouse stores data and shows what is available, but it does not tell you what any of it means. For many years, that was fine because a human analyst sat between the data and the decisions. The analyst understood the meaning, knew the definitions and which source was reliable, and knew who to ask if something looked wrong. The context layer already existed. It was made of people.
Governance was our first attempt to write the context down, and data catalogs added real value by inventorying assets, tracing lineage, and documenting the meaning of key terms. However, a catalog is reference material. If you change an entry, you have changed the documentation, but it does not automatically update a dashboard or calculation. A context layer is different because its definitions are used at the moment a question is answered, rather than simply stored for someone to find and interpret. And AI doesn’t have a friend to phone. Hand a model a raw schema, and it confidently resolves every ambiguity, often producing a result that is plausible but wrong.
Strong data infrastructure is necessary but not sufficient. That’s why, at MetLife, we’re ensuring domain experts actively define what terms mean. Leaders invest in that work because they view data as a strategic asset. This is not simply a data engineering problem. It is a “what is the company actually saying” problem, and it requires a genuinely curious team to do it well.
Q: When you talk about a context layer, what role do semantic models, ontologies, knowledge graphs, and metadata each play within that foundation?
They are the pieces that make up the context layer, each with a different job.
Semantic models define the business logic: what a metric is, how it’s calculated, which dimensions can legitimately slice it, and which grain it lives at. This is where “persistency” stops being a word people use loosely and becomes a single governed definition with clear ownership.
Ontologies define core business concepts and the relationships between them (e.g., how customer, policy, plan sponsor, and claim relate). They are where the deterministic logic lives, the constraints you use to tell a probabilistic model which paths are valid.
Knowledge graphs make that structure real. For example, the ontology says a policy can have beneficiaries and a plan sponsor. The graph connects this policy to its actual beneficiaries, sponsor, and the claims against it. In short, the ontology defines what can exist and how it can connect; the graph represents what has been recorded. This enables an agent to get from a question to the specific entities that answer it.
Metadata carries the operational and governance context wrapped around all of it: lineage, ownership, sensitivity, freshness, and quality. It lets a system know that a number is right and that it is allowed to show it to you.
These aren’t four separate initiatives. The value shows up when they’re wired together and pointed at the same decision.
Q: How does a context layer help bridge the gap between how the business understands information and how AI systems interpret it?
We spend months teaching a new person the vocabulary, rules, and exceptions of the business before we let them work unsupervised. Yet we often give AI access to a database, ask a complex question, and then act surprised when the answer falls short.
The gap is almost never technical. It’s that the business runs on knowledge nobody ever wrote down:
- Two teams use the same word for different things and have been quietly reconciling it in meetings for years
- A field means one thing for a legacy block and something else after a system migration
- One team applies a rounding convention no one else knows about
People learn these nuances through conversations, experiences, and correction. A model does not have that path to understanding.
A context layer closes that gap by turning institutional knowledge into structured, governed assets that AI can use as it reasons, including definitions, hierarchies, valid values, permissions, and lineage. It has to be a two-way street. The business needs to see its own vocabulary reflected back, or it won’t trust the output, no matter how good the technology is.
Q: What are some of the most common mistakes organizations make when trying to provide business context to AI initiatives?
The four most common mistakes that I’ve seen are:
- Starting with the technology instead of a decision: Teams pick a platform, then go looking for a problem. The right sequence is to find one workflow where people are demonstrably burning hours debating whose number is right, and model only what that workflow needs.
- Trying to map the entire enterprise before delivering anything: This leads to a beautiful context layer with no users, and business partners wondering what you spent so much time and money building. Start with the minimum viable ontology, tied to a real problem, and earn the right to expand.
- Assuming the AI can define the terms for you: This is the most tempting shortcut because you can point a model at the data, ask it to generate definitions, and what comes back reads beautifully. But a model can only infer meaning from what it can see, and a lot of our meaning isn’t in the data itself. The result you get back is the same ambiguity you started with, restated more confidently and now considerably harder to spot. At MetLife, we use AI to create a draft, but our subject matter experts always own the final version.
- Treating it as a data team deliverable: If the business isn’t in the room defining the terms, you haven’t built a context layer. You’ve built one more opinion about what the data means.
Q: Can you share a practical example where adding business context significantly improved an AI use case or business outcome?
The clearest one for us is self-service analytics: letting people ask questions of our data in natural language rather than relying on their data partner or a static report.
Take a fundamental term such as sum assured. Ask anyone in insurance what it means, and they’ll tell you it’s obvious. It is not. It can mean the original face amount at issue, the current in-force amount, or the coverage after riders and adjustments. Three different numbers, all legitimately called sum assured, each of them correct for the team that uses it that way.
Now point AI at raw data and ask it about total coverage. It will choose one of the three without telling you a choice existed. What comes back is a real number, calculated correctly, that quietly answers a different question from the one you intended to ask.
Dates are the same story, and they compound. Issue date, effective date, and policy commencement date get treated as interchangeable. They are not. They mark different business events. When a system silently substitutes one for another, you don’t find out in the query. You find out weeks later in a reconciliation that will not tie.
And that is what makes this failure different from the ones we are used to managing. When a system breaks, it produces an error, alerts us, and someone fixes it. But when a definition is wrong, nothing breaks, and no error appears. The only person capable of catching it is someone who already knows which of the definitions should have been used, which puts them right back in the middle of every question, verifying numbers instead of working on the problems that need their expertise.
A context layer changes what the model has to work with. It doesn’t just hold the agreed definition; it records where more than one legitimate definition exists, what each is called, and who owns it. That is what allows the system to recognize that “total coverage” is an ambiguous question rather than guessing at it. Where the context (who is asking, and for what) points to one definition, it uses that one and says so. Where it doesn’t, it asks the person to choose.
At MetLife, we’re at the point in our journey where we’re beginning to see a shift in the questions coming to our team from “Is this number right?” to “What should we do about it?” The unlock isn’t speed. It’s that people stop double-checking the answers.
Q: As organizations adopt agentic AI and autonomous decision-making systems, how does the need for a strong context layer become even more critical?
Everything I have described gets considerably harder when a system moves from just answering questions to acting. In analytics, a person reads the answer before anyone acts on it, and their experience is the control. They are the one who notices when a number looks wrong. An agent executing a multistep workflow has no such checkpoint. It uses the output from step one as input for the next, and a small misunderstanding at the top compounds through the chain. By the time anyone notices, the error may already be embedded downstream in a process.
Agents also need a type of context that analytics never needed in the past. Not only do they need to know what the data means, but also what is happening right now, what was decided before and why, what the agent is permitted to do, and where it must stop and ask for human input or review. So, those guardrails must be built into the environment in which the agent operates. The context layer is the source of meaning, not the whole control system. But every control around the model can only enforce a definition someone has written down and the business has agreed to. In a regulated industry, we have to be able to explain why a system did what it did: which policy applied, which definition was used, and which record it read.
AI models are broadly available to everyone, but your company’s context is uniquely yours. Get it right, and it compounds; get it wrong, and it scales the mistake.
 Elevate Your Personal Brand