What Is a Chief Data Officer in 2026? Many people working within the data industry are saying the same thing: the role of the Chief Data Officer (CDO) has changed – but how? CDO Magazine began an expert survey to find out. We recent...
Generative + Agentic AI: Moving From Experimentation to Enterprise Scale Generative and agentic AI are making their way into enterprise production, bringing new questions for Chief Data Officers (CDOs) and other data and AI leaders responsible for making these technologies...
Leadership Summit – Cincinnati – Westin Cincinnati - Downtown – November 19, 2026 Join top AI and Data leaders in Cincinnati to explore the strategies, governance, and innovations driving enterprise performance. Connect, learn, and gain actionable insights — reserve your seat today...
AI Governance
Approval Is an Event, but Judgment Is a Capability: Dr. Yodit Ayalew on Human Oversight in AI Governance
Q&A with Yodit Ayalew, Ph.D., Federal Data and AI Leader

Written by: Marcy Tillman | Director, Content Strategy, CDO Magazine
Updated 11:00 AM EST, November 19, 2026
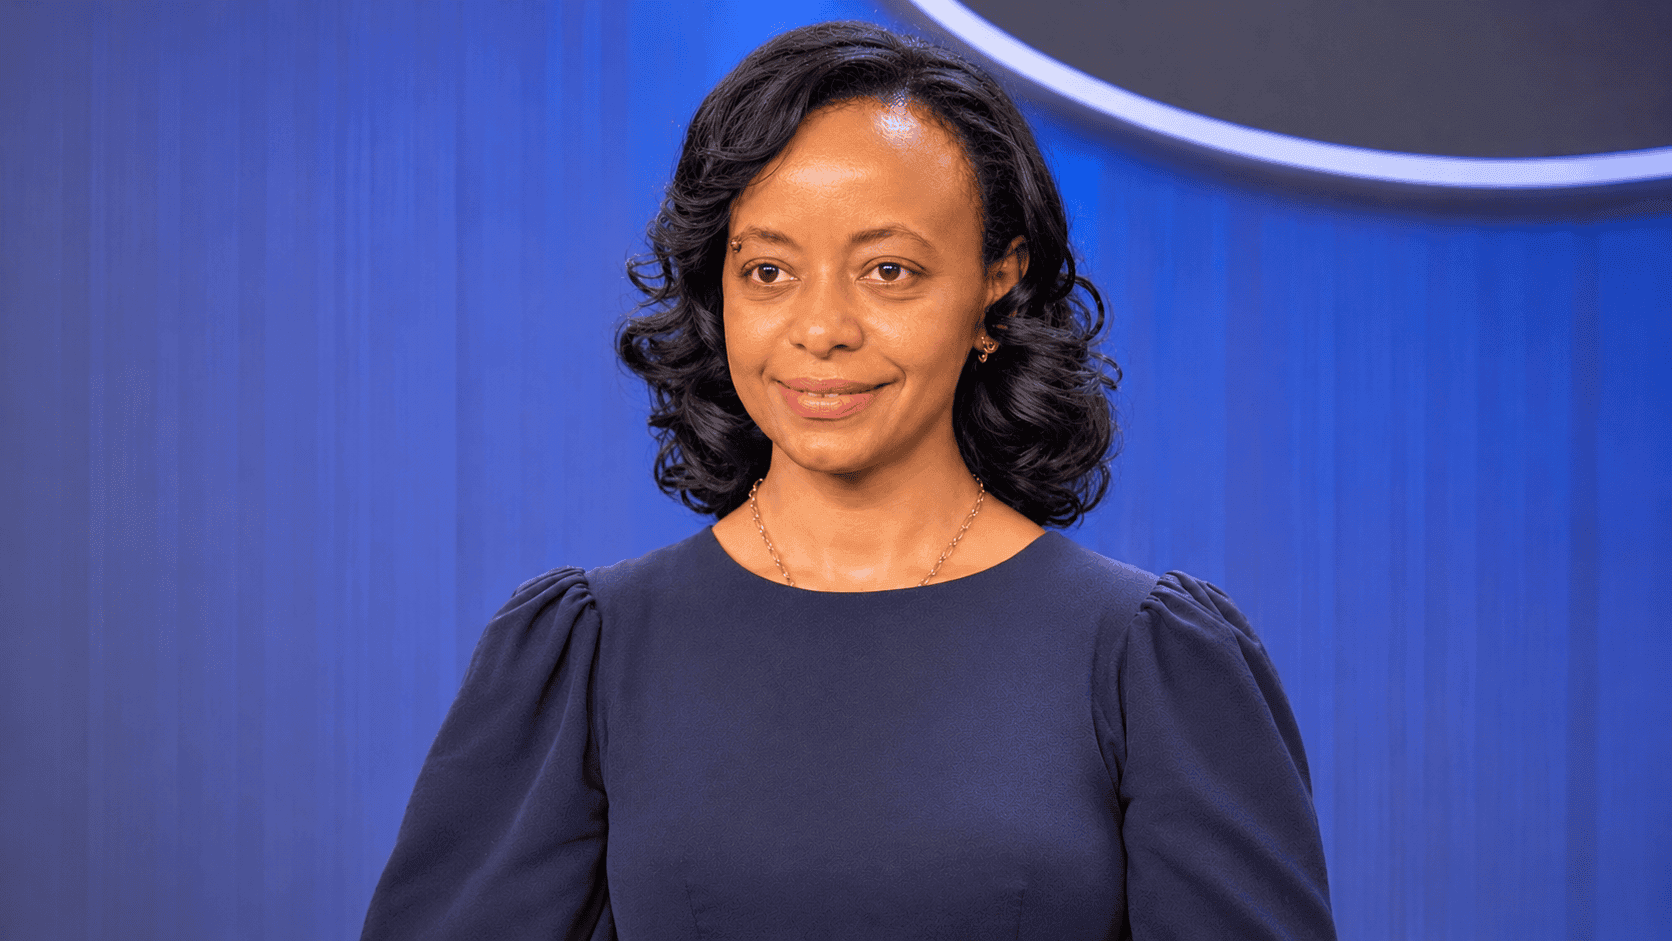
Drawing on her research and data governance experience, Dr. Yodit Ayalew shares how organizations can tell whether reviewers are truly questioning AI recommendations, and who should answer for AI-assisted decisions.
Imagine a caseworker reviewing a public benefits application who relies on an AI-generated summary to help determine whether someone qualifies for assistance. What if that summary leaves out important information? If questioning the system requires extra documentation or an escalation, how likely is the caseworker to challenge it?
For Dr. Yodit Ayalew, a federal data and AI leader and researcher, scenarios like this one illustrate a weakness in how organizations approach human oversight. By the time a recommendation reaches a human reviewer, important decisions have already been made about what data the system uses and which information it considers relevant.
In this Q&A, Ayalew discusses the limits of human oversight, why accountability starts with data decisions, and the practical steps chief data officers (CDOs) and other data leaders can take to strengthen it.
Edited Excerpts
Q: What led you to focus on human judgment and accountability in AI?
When I started my doctoral research, human judgment wasn’t necessarily what I set out to study. My research focused on criminal investigative analysis, where I developed a framework that combines graph-based retrieval, generative AI, and explainable AI to help investigators identify connections across crime data.
For example, imagine two crimes committed in different locations, around the same time, with similar methods. An AI system might identify a possible connection between them and show exactly which pieces of information led to that conclusion. But does that mean the two crimes were committed by the same person? Of course not. An investigator still needs to examine the circumstances and look for evidence that supports or challenges the connection.
That example helped me think more critically about the limits of explainability. Just because we can explain how AI arrived at an answer doesn’t mean we have enough justification to act on it.
Similar questions come up across data governance more broadly, particularly around data ownership, access, and authorization. Just because we have the technical ability to bring information together and make it available doesn’t necessarily mean every use of that information is appropriate or justified. Someone still has to decide how it should be used and who is accountable for the outcome.
I realized we were investing tremendous effort in making AI systems more capable and explainable, but not giving the same attention to whether people are exercising sound judgment when they use the outputs. That’s what led me to develop Judgment-Centered AI Governance. Having a human involved in the process is important, but what matters is whether that person can genuinely question, understand, and take responsibility for the decision.
Q: Why can an AI system that works as designed still create an accountability problem?
Because accuracy answers a narrower question than accountability does. An accuracy test tells you whether an output matches a chosen target. It cannot tell you whether that target was legitimate, or whether the person affected can understand and contest what happened.
Australia’s Robodebt scheme is the clearest example I know. It was rules-based automation rather than generative AI, and it largely did what it was designed to do: average annual income across fortnightly periods to raise welfare debts. The calculation was consistent. The premise was wrong. A Royal Commission later called the scheme “a crude and cruel mechanism, neither fair nor legal.”
For CDOs, this is where the work starts. Most of those premises are data decisions: which variables stand in for the thing we actually care about, which records count as authoritative, which thresholds trigger action. The CDO should own whether data is fit for the decision it supports. That is a harder standard to meet than accuracy.
Q: What’s the difference between human approval and meaningful human judgment, and where do organizations fall short?
Approval is an event. Judgment is a capability. A person can click “approve” on every case in a queue without ever being in a position to disagree. Meaningful judgment means the reviewer can see the evidence and its uncertainty, weigh circumstances the system does not capture, and reach a different conclusion without penalty.
Where organizations fall short is that they put the review in the wrong place. It sits at the final screen, after the consequential choices have already been made. I’ve seen a similar challenge in enterprise data governance. Different teams may have completed their respective reviews, but that doesn’t necessarily mean someone has examined the broader implications of using that information to support a decision. By the time someone is asked to approve the final result, those earlier assumptions may already be treated as settled.
My advice to executives is to trace one decision in both directions.
- Backward: Who selected the variables? Could a reviewer challenge those choices, or only override a single output?
- Forward: Could the affected person get an explanation and a real correction?
If the answer in either direction is no, the approval step offers procedural comfort and very little control.
Q: How can leaders tell when employees feel pressured to accept AI recommendations, and what can they do?
Look at the workflow before you look at the culture. In most organizations, nobody says “just accept the recommendation.” The design says it for them. Accepting takes one click. Rejecting requires a written justification and an escalation. If disagreeing with the system costs a reviewer far more time than agreeing with it, you have built a rubber stamp, whatever the policy says.
A low override rate proves very little on its own; it may simply mean the system is good. The more revealing measure is audit discordance, the gap between what reviewers approve and what an independent check of a sample later finds wrong. For example, a data leader could take a random sample of 100 AI-assisted decisions that employees approved and have an independent team review them against the original evidence, without seeing the AI recommendations. Suppose that review finds eight decisions with material errors that the original reviewers missed. That’s worth investigating. The goal isn’t to blame employees, but to understand whether human oversight is actually working.
Q: When an AI-assisted decision involves multiple teams, systems, or vendors, how can organizations establish clear accountability?
Traceability and accountability are two different things. A log can tell us which system changed a record or who accessed certain information. But that doesn’t necessarily tell us who is responsible for explaining a decision or correcting something that went wrong.
In large organizations, responsibility fragments easily when an initiative spans multiple teams. The data owner authorizes the use of data, engineers build the pipelines, security teams establish controls, platform teams manage the infrastructure, and a program office ultimately uses the information. Everyone has a role, and each team may fulfill its responsibilities. But who is accountable for how the resulting capability is used?
My recommendation is to establish a clearly identified mission owner who is accountable for the consequential outcome, with defined responsibilities at every major handoff. A vendor may operate part of the system, and different teams may manage its components, but accountability has to sit with someone who can actually exercise authority, not be spread across a committee.
Q: As AI systems move from making recommendations to independently executing actions, how does that change the accountability challenge? Where should organizations draw the line between delegating tasks and transferring responsibility?
The accountability challenge grows because an AI system can now act before anyone reviews the result. It can update a record, send a notice, or trigger another system. Each of those actions may be permitted on its own, and together they can still produce an outcome nobody approved. Leaders have to think about the whole chain of actions, not just each step.
I don’t think that means a person has to approve every routine action. Where the line falls for any task depends on two things: how hard the action is to undo, and how much evidence you have that the agent handles it reliably. So an agent should earn its authority. I’d start by writing down everything each agent can actually do and marking which actions are hard to undo or directly affect people. Many organizations haven’t done this, and it’s usually eye-opening.
From there, start small. Let the agent draft before you let it send. A coding agent that proposes changes hasn’t shown it can safely push them to production. Add permissions one at a time, and only after you’ve watched the agent handle that specific action reliably.
The limits also have to live outside the agent: access permissions, transaction limits, a record of every action, and a way to stop it that doesn’t depend on the agent cooperating. Test the stop before you need it.
And before anything goes live, put one person’s name on it. That person watches how the agent performs, investigates when something goes wrong, and makes sure the people affected get an explanation and a fix.
Organizations can delegate execution. They can’t delegate responsibility for what they authorize, how they supervise it, and what they do when something goes wrong.
Q: What role should executives and boards play in ensuring employees can question or stop an AI-enabled process?
Executives decide whether challenging an AI system is a protected duty or a career risk. They make that choice less through statements than through budgets, performance targets, escalation rules, and how they respond when someone brings them uncomfortable evidence.
A protected challenge channel needs a named recipient, a response deadline, and protection for good-faith concerns. When a team pauses a model over a concern that proves valid, leaders should recognize it publicly; nothing signals more clearly that challenge is welcome. A board that has never heard of a single challenge should treat that silence as a warning sign.
The question I ask every leader is simple: who will answer for this decision if it is questioned a year from now? If they cannot name that person today, ownership is still theoretical.
Q: What’s something about AI governance you’ve changed your mind about, and what would you tell data leaders starting out?
Early in my research, I put a lot of weight on explainability. I still think explainability matters, but I no longer believe it carries that much of the load.
The bigger shift for me has been in where I look for risk. I used to focus on systems that failed in obvious ways. Over time, I’ve become more concerned about systems that perform well. After a year of good results, a tool tends to stop being treated as a tool and starts being treated as part of the process. The scrutiny fades as the system becomes familiar.
A practical step I’d recommend is to agree in writing, before a system goes into production, on what would cause you to pause or retire it, and to name the person with the authority to make that call. That conversation is much easier to have at the start than two years later.
I’m excited about what AI can do, and I’ve seen it make real work better. That is exactly why I try to be careful about which capabilities we fully automate and which should stay with people.
Professional Biography
Yodit Ayalew, Ph.D., is a federal data and artificial intelligence leader. She holds a Ph.D. in Artificial Intelligence, an M.S. in Applied Data Science, and a B.S. in Industrial Engineering. Her independent research centers on Judgment-Centered AI Governance (JCAG), which examines how institutions preserve human judgment and accountability in AI-enabled decisions. That work includes JCAG-A, its extension to agentic AI systems, and Evidence-Gated Delegation (EGD), an approach to expanding AI agents’ authority based on evidence of safe performance. She is the author of the forthcoming book When Machines Decide Quietly: Preserving Human Judgment, Accountability, and Moral Courage in the Age of AI.
Disclaimer from Dr. Ayalew: The views and opinions expressed in this Q&A are solely my own and are shared in my personal capacity. They do not necessarily reflect the views, positions, or policies of the U.S. Department of Homeland Security (DHS), U.S. Immigration and Customs Enforcement (ICE), or the United States Government.

 Elevate Your Personal Brand


